White paper
What actually bites teams in production
Most Linkerd installs go fine. The problems show up later: the issuer cert expires, and nobody wrote down the rotation procedure. The cluster grows, and the control plane has no resource limits. A Kafka pod gets meshed, and the proxy starts interfering with traffic because the port was never marked opaque. This checklist covers the 6 areas where teams get burned:
- Installation and GitOps: Helm config in Git, rollback procedure written down and tested (if you haven’t tested it, it’s not a procedure)
- Certificates and identity: Trust anchor and issuer cert setup outside the CLI, cert-manager integration, documented rotation procedure for both
- Control plane HA: High availability mode, resource requests and limits on every control plane pod, health monitoring over time
- Proxy and workload tuning: High-traffic and stateful workloads (databases, Kafka, large monoliths), opaque ports, explicit gRPC configuration
- Observability and alerts: Prometheus into Grafana, centralized log aggregation, a single incident dashboard, alerts for cert expiration before it pages you
- Environment parity: Same Helm and GitOps workflow across dev, staging, and prod; at least one upgrade and one issuer rotation practiced in a lower environment before prod
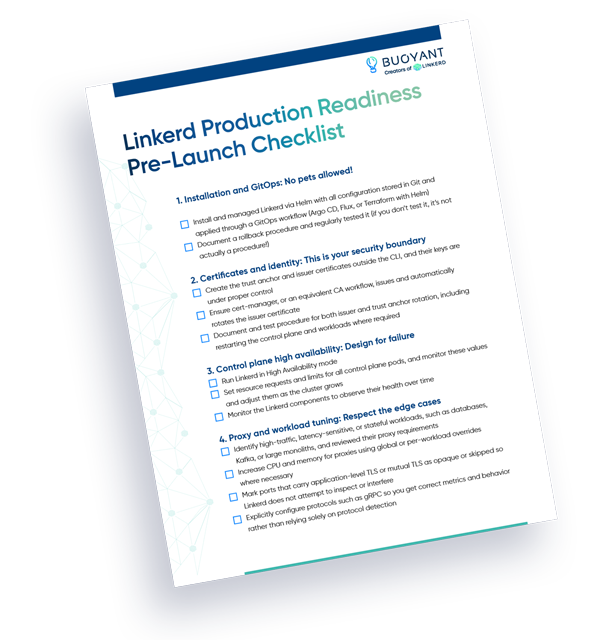
Get your personal checklist copy
Make it yours. Work through every item, check off as you go, before you push to production.
Loading form: Form on /download/linkerd-production-readiness-pre-launch-checklist
From Buoyant, creators of Linkerd. No spam.